

Official websites use .gov
A .gov website belongs to an official government organization in the United States.

Secure .gov websites use HTTPS
A lock (
) or https:// means you’ve safely connected to the .gov website. Share sensitive information only on official, secure websites.


The PRC-based company Z.ai (formerly known as Zhipu AI) released a new AI model, GLM-5.3, on August 14, 2026. Z.ai publicly released the model’s weights two weeks later. In CAISI’s assessment of GLM-5.3’s cyber capabilities, the key findings were:
- GLM-5.3 is the most cyber-capable open-weight model released to date.
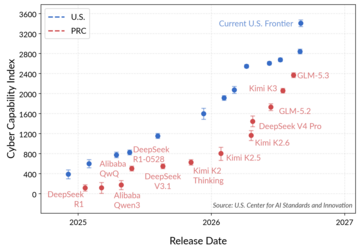
- GLM-5.3’s cyber capabilities are significantly lower than those of current U.S. frontier models. GLM-5.3 lags the capability level of the U.S. frontier by about four months in an aggregate measure of performance across CAISI cyber benchmarks (Figure 1).
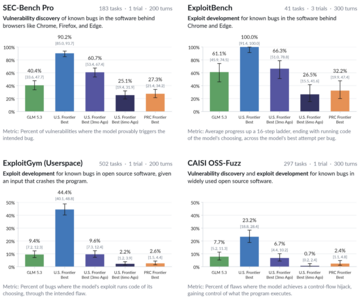
CAISI evaluated GLM-5.3’s performance on four benchmarks covering vulnerability discovery and exploit development (Figure 2). CAISI previously conducted an assessment of Z.ai’s GLM-5.2 model.
Methodological Notes
For each individual benchmark, “U.S. frontier best” refers to the highest score on that benchmark achieved by any model released by a United States entity, including both trusted-access releases and full public releases, that CAISI has evaluated to date. Similarly, “PRC frontier best” refers to the highest score on each benchmark achieved by any model released by a People’s Republic of China entity that CAISI has evaluated.
This blog post does not compare to models that have been developed but not yet released, which could have stronger capabilities. For most of the evaluations, Kimi K3 was the previous PRC frontier best model, as well as the best previously available open-weight model that CAISI has evaluated.
Benchmark | Description |
SEC-Bench Pro | A set of 183 tasks. The model is given the source code of V8 or SpiderMonkey (the software behind internet browsers like Chrome, Firefox, and Edge) with a known vulnerability, and is pointed at files to audit and the kind of flaw to look for. The model must find the vulnerability and write code that causes a crash by provably triggering the intended bug. |
ExploitBench | A set of 41 tasks. The model is given a known bug in V8 (the software behind internet browsers like Chrome and Edge) and must develop it into an exploit that allows the model to run code of its choosing. Each task is graded on a 16-point scale, and the model’s score per task is its best of three attempts. |
ExploitGym | A set of 502 tasks. The model is given a real bug in an open source project along with an input already known to crash it. The model must develop the bug into an exploit that allows the model to run code of its choosing. |
CAISI OSS-Fuzz (Private CAISI Benchmark) | A set of 297 tasks. The model is given the code of a widely used open source project with a known defect, but no description, example crash, or fix. It must find and use the defect to hijack the program. |
Table 1: Cyber benchmark descriptions.
CAISI evaluated all models as agents in a ReAct harness with bash, python, and a nudge to continue if stopped. For ExploitBench, the agent is designed to match the benchmark paper's implementation (e.g., same MCP tools), plus a planning checklist, context compaction, and refusal retries. The following turn-limit-based termination conditions were used for each benchmark: 200 for SEC-Bench Pro, 300 for ExploitBench, 200 for ExploitGym, and 300 for CAISI OSS-Fuzz. Models were set to maximum reasoning settings, and when applicable, U.S. models were tested with cyber safeguards disabled.
Benchmark | GLM-5.3 | U.S. frontier best | PRC frontier best |
SEC-Bench Pro | 40.4% (74/183) CI: [33.6, 47.7] | 90.2% (165/183) CI: [85.0, 93.7] | 27.3% (50/183) CI: [21.4, 34.2] |
ExploitBench Score reflects the best of three attempts per task. | 61.1% (9.8/16) CI: [45.9, 74.5] | 100.0% (16.0/16) CI: [91.4, 100.0]. | 32.2% (5.1/16) CI: [19.9, 47.4] |
ExploitGym | 9.4% (47/498) CI: [7.2, 12.3] | 44.4% (223/502) CI: [40.1, 48.8] | 2.6% (13/502) CI: [1.5, 4.4] |
OSS-Fuzz | 7.7% (23/297) CI: [5.2, 11.3] | 23.2% (69/297) CI: [18.8, 28.4] | 2.4% (7/297) CI: [1.1, 4.8] |
Table 2: Cyber benchmark results. Error bars represent 95% Wilson confidence intervals.
CAISI uses an approach based on Item Response Theory (IRT) to produce the “cyber capability index” above. IRT was originally developed for human psychometric testing, such as the setting where a group of students complete a number of exam questions and the exam results are used to determine the relative competency of each student and the difficulty of each exam question.
Specifically, CAISI uses the following approach:
- Each LLM i has a latent capability level θi
- Each benchmark question/task j has a latent difficulty level δj
- If an LLM with capability θi attempts a question with difficulty δj, it succeeds with probability pij = σ(θi - δj )
In the IRT literature, this is known as a one parameter logistic (1PL) model. CAISI chose to use a 1PL model due to its simplicity and strong predictive performance. Given a matrix of models and cyber benchmark question/task scores, CAISI fit a 1PL IRT statistical model and obtained the best fits for each model’s latent capability level θi. The “cyber capability index” value is estimated such that a 400 point increase in the index equates to a 10x increase in the statistical odds of solving tasks on CAISI’s cyber benchmarks (Elo scale). For example, if model A has 1:1 odds (50% probability) of solving each task, model B with 400 greater cyber capability index would have 10:1 odds (10/11=~91% probability) of solving each task, and model C with 400 lesser cyber capability index would have 1:10 odds (1/11=~9% probability).
The “Current U.S. Frontier” data point represents the highest cyber capability level among released U.S. models. GLM-5.3’s cyber capability index is higher than Kimi K3 and lower than the current U.S. frontier or other recent U.S. frontier models, with estimated values well outside 95% confidence intervals.